1.1 The wrong question
Frontier language models went public in 2023. Since then, every major engineering organization in automotive, aerospace, medical devices and industrial automation has been handed the same directive: put AI into the safety-critical workflow.
If you lead one of those teams, you've probably heard the question that comes next. It goes to vendors, consultants and internal architecture teams alike:
Which AI tool should we buy for our MBSE stack?
This chapter explains why that assumption fails. The rest of the book shows what to do about it.
Why the title says MBSE for AI
You may have noticed that the title reads the other way round from what the market is selling. That's deliberate. It's the whole argument of this book in three words.
AI for MBSE
AI serves the modeling tools you already have.
A language model is bolted onto Capella, Cameo, Polarion or DOORS. The data model, file formats and validation stay as they were, designed for human authors.
Result: faster first drafts, then schema drift, invented trace links and a painful audit.
MBSE for AI
The modeling language is redesigned so AI can be its primary author.
Plain text, strict types, a deterministic validator and a skill file for every file type. Engineers review, decide and sign.
Result: speed that still holds up in front of the auditor.
The vendors are building AI for MBSE. This book is about MBSE for AI: changing the engineering model itself so machine authors can work in it safely, and people stay accountable for what ships.
What the vendors are selling
Every major MBSE platform was designed between roughly 2005 and 2012: IBM Rhapsody, Dassault CATIA Magic (formerly No Magic Cameo), Siemens Polarion, Eclipse Capella and PTC Integrity Modeler.
Each one has now bolted a large-language-model interface onto its existing data model. The marketing reads the same in every announcement:
- Natural-language requirements
- AI-generated test cases
- Auto-traced safety goals
- Intelligent change-impact analysis
The demo videos look incredible. The keynote screenshots are crisp.
Two architectural worlds
Designed for human authors (2005 to 2012)
- Graphical editor as the primary interface
- Semantics carried by UI convention
- Validation only at save (seconds)
- Errors written for humans to read
- Artifacts in proprietary binary or XMI
- Change management as a separate subsystem
Required for AI authors (2024 onward)
- Plain-text DSL as the primary interface
- Explicit grammar and typed relationships
- Continuous, deterministic validation (10 ms)
- Structured error codes an agent can parse
- Artifacts in readable, diff-friendly text
- Change management inside the model
What happens at audit
A safety auditor doesn't evaluate the user interface. Whether it's an ISO 26262 assessor, an EU notified body, a DO-178C DER or an IEC 61508 functional-safety reviewer, they evaluate the artifacts.
When an LLM produces artifacts through a 2008-vintage tool, expect three failure modes:
- Schema drift. The LLM invents fields the tool's schema doesn't represent (notesField, priority2, legacyTag). The auditor finds items carrying custom attributes whose meaning is defined nowhere. Rejected under ISO 26262-8:2018 §6.4.2.
- Trace-link hallucination. The LLM produces a plausible requirement and a trace link that looks valid. At audit, the target safety goal doesn't exist, or it exists with the wrong ASIL. Rejected under ISO 26262-8:2018 §7.4.2 or DO-178C §6.5.
- Audit-trail opacity. The model holds the result of the AI's reasoning but no record of the reasoning itself. When the auditor asks why this ASIL?, the only answer is because the model said so. Rejected under ISO 26262-2:2018 §5.4.3.
A more precise diagnosis
The AI industry usually blames model capability. The models aren't good enough yet, and better ones are coming. Retrieval will fix hallucination. Better prompting will fix schema drift.
That's a category error.
The problem isn't in the model. It's in the interface between the model and the artifact: the tool's data model, file format and validation pipeline. That interface rests on an assumption that no longer holds, namely that the only intelligent agent reading or writing the model is a human.
We've done this before
Software engineering has made this kind of transition before.
In the early 1990s, the safety-critical industries used Ada, MISRA-C and assembly. When object-oriented design arrived, the first response was to retrofit. Ada-95 added inheritance to Ada-83, MISRA considered object-oriented subsets, and various safer C++ dialects were proposed.
By the late 1990s, the limits of retrofitting were obvious. The industries that captured the productivity benefits did it by adopting new languages designed for safety-critical object-oriented programming: Ada-2012 with SPARK, and later Rust.
What I learned at Continental
I spent fifteen years at Continental Automotive authoring the architecture DSL that today generates ASIL-D software shipping in over ten million vehicles.
The whole time, I was solving the same problem the AI vendors are solving now. The difference: my intelligent agent was a code generator, not a language model.
The lesson generalizes.
That's what Sylang is
Sylang isn't a language that AI can use. It's a language designed for AI to use. Humans are the secondary audience, and they get a much better authoring experience as a bonus.
Three numbers tell the story.
- 22 file types. One per engineering artifact: requirements, hazards, blocks, interfaces, FMEAs, fault trees, tests, agents, sprints, specifications and dashboards. Every file has exactly one header. Every artifact has a single addressable home.
- 47 relationship keywords. derivedfrom, allocatedto, satisfies, mitigates, causedby, verifiedby, decomposesto and the rest. Each is a typed edge in an ontology the validator enforces deterministically. The model is a graph an agent can walk without guessing.
- One Markdown skill file per file type. When an AI agent meets its first
.reqor.flrfile, it loads the matching skill: eighteen kilobytes of grammar, conventions, pitfalls and examples. From then on, it knows how to author that file correctly. The language teaches itself.
A sample requirement
Here's what a requirement looks like in Sylang. Read it first, then I'll explain why its shape matters.
use functionset EpbFunctions
use safetygoalset EpbSafetyGoals

hdef requirementset EpbSafetyRequirements
  name "EPB Safety Requirements"
  safetylevel ASIL-D

  def requirement REQ_EPB_002
    name "Prevent engagement above 10 km/h"
    description """
      The EPB shall not initiate an engage sequence when vehicle speed
      exceeds 10 km/h, regardless of the source of the engage request.
    """
    reqtype safety
    safetylevel ASIL-D
    status approved
    derivedfrom ref safetygoal SG_NoUnintendedEngagementAtSpeed
    implements ref function EngageController
    allocatedto ref block EpbController
Every line is typed.
safetylevel ASIL-D isn't a string. It's an enum value, checked against the seventeen legal safety levels. derivedfrom ref safetygoal isn't a hyperlink either: it's a typed edge to a safety goal elsewhere in the project. The validator rejects the file at parse time if that goal doesn't exist or has the wrong type.
What comes next in this chapter
Over the next five subchapters, I'll:
- (1.2) Show why today's MBSE stack falls over under AI authorship
- (1.3) Explain what changes operationally when AI can read and write the model directly
- (1.4) Lay out the cost-of-quality math: the safety case today vs. on Sylang
- (1.5) Compress the whole thesis into a three-paragraph CTO pitch you can carry in your head
- (1.6) Map the rest of the book to the four reader paths: leaders, engineers, AI builders and auditors
If you're a leader with only an hour for this book, those five subchapters are the hour. Everything after them is the evidence.
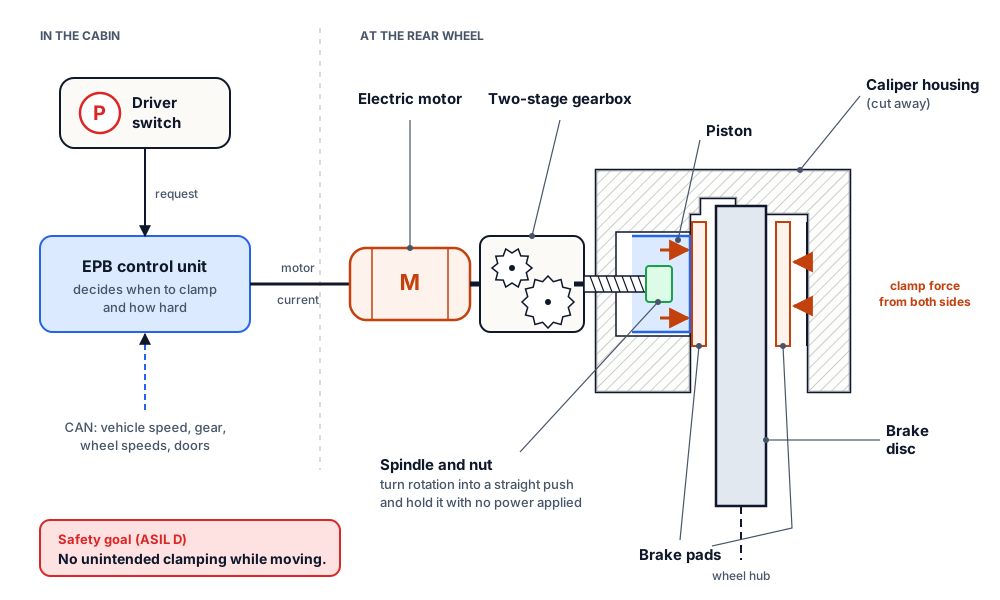
The four anchors cover automotive, aerospace, medical and industrial work. They are an Electric Parking Brake (ISO 26262 ASIL-D), autopilot envelope protection (DO-178C DAL-A) and an insulin infusion pump (IEC 62304 Class C). The fourth is collaborative-robot safe zones (IEC 61508 SIL-3 / ISO 13849 PL-e).
1.2 Why the incumbent stack fails under AI authorship
Subchapter 1.1 named the symptoms: audit failures, schema drift, trace-link hallucination. This subchapter goes one level deeper, to four architectural decisions shared by every dominant MBSE platform. Each was defensible in its time. None survives the shift to AI authors.
Decision 1: models stored in proprietary binary or XMI
Every dominant MBSE platform stores its models in a format the vendor controls.
| Tool | Format | Type |
|---|---|---|
| Eclipse Capella | .aird / .melodymodeller / .afm | EMF XMI 2.0 + Arcadia extensions |
| IBM Rhapsody | .rpy / .sbs | Compound XML + binary refs |
| Dassault CATIA Magic | .mdzip | ZIP container of XMI + binary indices |
| PTC Integrity Modeler | .iuc | Compound binary |
| Siemens Polarion | (relational schema, web service) | Database-backed REST |
For human authors, these formats worked well. They were compact, resistant to text-level corruption and internally cross-referenced. For AI authors, three properties rule them out:
- Not natively diffable. An AI's proposed change shows up as a binary or XMI diff that doesn't match any conceptual change. Git blame, log and bisect become useless.
- Not addressable by stable identifier. Artifacts are referenced by vendor-controlled GUIDs. The agent has to translate human-meaningful names into GUIDs, and that translation step is a prime source of trace-link hallucinations.
- Cannot be authored without the tool. An agent can't generate a valid Rhapsody
.rpyfrom a text transcript. The tool must be running, licensed and connected, which kills the concurrency that makes AI authoring worthwhile.
Decision 2: validation waits until save
The incumbent tools validate on save, or through a background polling validator. Latency runs to seconds. Error messages are prose written for a human reader.
Human authoring cadence
A few changes per minute, sustained over hours.
Two to ten seconds of validator latency: invisible.
Error message in prose: The relationship at line 42 has an invalid target type. The human reads it, applies judgment and fixes it.
Verdict: the design fits the operator.
AI authoring cadence
Tens of operations per second, sustained indefinitely.
Two to ten seconds of latency: a bottleneck. The agent waits more than it reasons.
Prose error: ambiguous. Change the target, or the relationship? The agent's guess is where schema drift comes from.
Verdict: the design is adversarial.
Decision 3: meaning hidden in graphical convention
In SysML, much of the meaning lives in graphical convention rather than in the data model:
- Element shape tells you part versus reference
- Connector style tells you aggregation, composition or association
- Color or a stereotype tag tells you the safety classification
A human reading the diagram absorbs all this without thinking. An AI agent reading the underlying XMI sees an array of Property elements behind a diagram exchange layer that is only partly implemented and varies by vendor. Two agents reading the same model can form different pictures, depending on which exchange layer they happen to use.
History offers a hard lesson here. Leveson and Turner (IEEE Computer, July 1993) documented at least three deaths and several severe injuries from the Therac-25 radiation-therapy machine between June 1985 and January 1987. The cause was divergent interpretation between the machine's software and its human operator. The technician's understanding, formed from console conventions, drifted away from the software's actual state.
Decision 4: change management lives somewhere else
Incumbent tools treat change management as a layer above the modeling tool. IBM DOORS Next uses Rational Team Concert. Polarion uses Polarion ALM. Cameo uses Teamwork Cloud.
Each records who changed what, when, and with what comment. The comment is free text, outside the artifact's validatable schema.
For a human author, the comment is enough. The engineer distills the reasoning into a sentence, and reviewers read that. For an AI author, the reasoning is longer and more structured than a comment can hold: the prompt, the retrieved context, the alternatives considered and the selection criteria.
How the four decisions lock together
The four decisions reinforce each other. A proprietary format makes deterministic validation expensive. Expensive validation makes structured error reporting impractical. Without structured errors, the model becomes opaque to outside review, and that opacity pushes change management out into a separate subsystem.
Subchapter 1.3 moves from diagnosis to design: what changes operationally when an AI agent is the primary author of the engineering model.
1.3 What changes when AI is the primary author
Subchapter 1.1 stated the thesis, and 1.2 explained why the incumbent stack can't deliver it. This one is the operational picture: what changes in your engineering organization the day after the switch. There are five changes, and you can check each one in your own workflow.
Change 1: artifact production gets two orders of magnitude faster
Public benchmarks of LLM coding throughput put a single agent at 50 to 150 substantive code changes per hour of continuous work. (SWE-bench Verified leaderboard, Princeton/CMU, accessed November 2025.)
For the same agent on a Sylang model, my working estimate is 30 to 80 substantive MBSE artifacts per hour. It's lower because safety-critical content needs more reasoning per artifact.
That figure overstates the practical gain. Review and acceptance stay with the human, and they don't speed up the same way.
End to end, from first draft to merged trunk, my working estimate for ASIL-D content is 4 to 8x. The bottleneck moves decisively from authoring to review.
Change 2: the review burden moves from authoring to acceptance
With human authors, the writer absorbs most of the cost of not producing bad artifacts. A competent engineer rarely commits malformed requirements or invalid trace links. Reviewers catch what's left.
With AI authors, the agent produces artifacts faster than an unchanged review process can keep up with. You can respond in one of two ways, and only one of them works over the long term.
Response A: less review per artifact
The reviewer reads each artifact more shallowly.
The residual error rate rises.
The safety case weakens.
End state: less safety, more audit risk and, at worst, a cancelled project.
Response B: machine-mediated review
A reviewer agent runs schema, traceability, and consistency checks.
The human reviewer focuses on flagged items and high-consequence content.
Sylang's deterministic validator and bilateral traceability rules give the reviewer agent high precision.
End state: better review quality at higher throughput.
Change 3: version control becomes the system of record
When MBSE artifacts are plain text under git, modern software practice applies unchanged: pull requests, code review, branch protection, CI and semantic versioning.
That's not a small change. Software teams have spent two decades refining these conventions. Regulated industries mostly couldn't adopt them, because MBSE file formats didn't support diffable review.
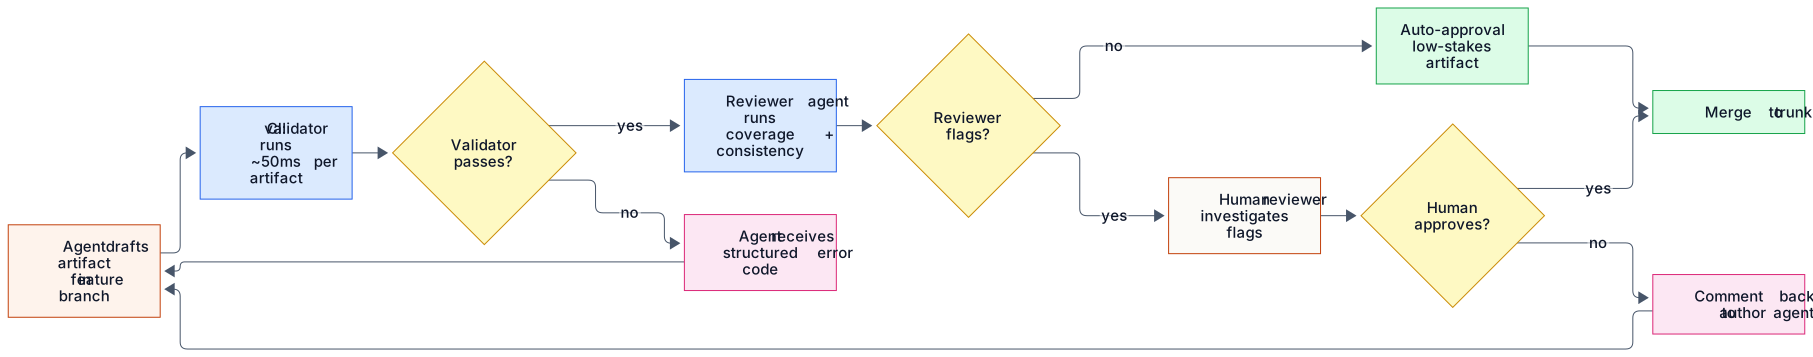
Three concrete benefits follow:
- An exact audit trail. Every change is signed by a committer (agent or human), timestamped and bound to a commit message.
- Branch protection on safety-relevant files. Changes to safety goals or ASIL allocations need explicit approval from designated reviewers (CODEOWNERS in GitHub, with equivalents elsewhere).
- Bisect works. When a downstream test fails, you find the commit that introduced the failure mechanically, and you see the artifact change line by line.
In Bookout v. Toyota Motor Corp. (Oklahoma District Court, October 2013), the plaintiff's expert testimony, reviewed publicly after the verdict, found several thousand global variables in Toyota's throttle-control software. That made it impossible to tell which change had introduced which behavior. The NASA review (Barr, NASA Engineering and Safety Center Technical Assessment Report, 2011) made similar observations.
Change 4: project management moves inside the model
Conventional MBSE keeps engineering artifacts in the modeling tool and project artifacts in Jira, Azure DevOps or ServiceNow. That split creates two failure modes, and AI authorship amplifies both.
- Scope ambiguity. The engineering model doesn't know which artifacts are in scope for the current sprint. An agent asked to change the model can't tell which changes are appropriate without outside context.
- Closed but not merged. A story marked done in Jira may leave orphan trace links that the artifact graph never reflects. Reconciliation is manual, and it piles up faster than people can clear it.
A task carries assignedto ref agent and outputfile references, and that's what makes the tracing work. The pattern has a precedent in infrastructure as code (Terraform, Pulumi, Kubernetes manifests). When automated agents make the changes, authority has to live in the same medium as the change.
Change 5: the safety case becomes machine-readable end to end
The safety case is a structured argument, backed by evidence from the engineering artifacts, that the system is safe enough for its intended use.
Today, the safety case is usually a Word document of several hundred to several thousand pages, produced near the end of the development cycle. Someone checks its consistency with the artifacts by hand. When an artifact changes after it's written, re-verification falls to the safety manager.
Sylang's .spec file type (Chapter 16) is the machine-readable alternative. Hierarchical sections hold def spec, def diagram and def table clauses. Each one queries the underlying artifacts through a small declarative DSL (source, where, groupby, orderby, columns).
Summary: the operational picture
Put together, the five changes describe a way of working that differs sharply from conventional MBSE in regulated industries.
- Artifact production is faster: roughly 4 to 8x end to end, on my estimate
- Review is more structured: machine-mediated triage
- Version control is the system of record: git is canonical
- Project management lives inside the model:
.agtand.spr - The safety case is alive: re-materialized on demand
None of these changes is unique to Sylang. In principle, any language built with enough design discipline could deliver them. What Sylang contributes is that discipline, bundled into one language you can adopt incrementally and that audits reliably.
Production conditions will lower all of these rates. My rough estimate is a 30 to 50% reduction, with the ratio between them roughly preserved. I'm preparing a more rigorous benchmark study for INCOSE Insight during 2026. Subchapter 1.4 turns these rates into cost-of-quality math.
1.4 The cost-of-quality arithmetic
An argument becomes a decision only once it has numbers. This subchapter works through the cost of ISO 26262 ASIL-D software development under three conditions: today's conventional baseline, the LLM retrofit and the redesigned language.
Baseline: conventional, human-authored ASIL-D
Over the past decade, industry benchmarks for ASIL-D development cost have settled into a narrow band.
Where the ASIL-D premium goes
The split varies by organization, but roughly, the premium divides across work products like this:
| Work product category | % of ASIL-D premium | ISO 26262 reference |
|---|---|---|
| Verification and validation (incl. FMEA/FTA) | 30-40% | Part 5 §9, §10; Part 6 §9-11 |
| Technical safety concept + architectural design | 12-18% | Part 4 §7 |
| Software architectural design + unit design | 12-18% | Part 6 §7, §8 |
| Software safety requirements | 8-12% | Part 6 §6 |
| Configuration, change, and documentation | 8-12% | Part 8 §6-§8, §10 |
| Safety case construction + audit support | 6-10% | Part 2 §6.4.4 |
| Hazard analysis and risk assessment (HARA) | 5-8% | Part 3 §6, §7 |
| Safety goals + functional safety concept | 3-5% | Part 3 §7, §8 |
Condition (b): the LLM front-end retrofit
As of 2025, the retrofits the incumbent vendors market target the authoring step of each work product.
- IBM Watsonx for Rhapsody (announced October 2023)
- Dassault Generative Experience for the CATIA/Magic family (June 2023)
- Siemens Industrial Copilot for Polarion (early 2024)
Marketing claims cluster around authoring-step productivity gains of 1.3× to 2×.
That's why the three failure modes from Subchapter 1.1 (schema drift, trace-link hallucination, audit-trail opacity) don't show up in those studies. They stop counting at commit to the model, not at acceptance through audit.
A complete accounting gives a different figure.
Condition (c): AI as primary author, with Sylang
The economic case rests on three effects: two direct, one structural. The figures below are my working estimates, built on the benchmarks above.
The three effects
- Direct effect 1: faster authoring. Take my 4 to 8× end-to-end estimate from Subchapter 1.3 and apply it to the 50 to 60% of the ASIL-D premium that authoring speed can touch. The first-order cut is 35 to 45% of the ASIL-D premium, or 7 to 13 percentage points of total engineering cost.
- Direct effect 2: a cheaper safety case. I estimate the conventional safety case (the 6 to 10% line) shrinks by about two-thirds, to 2 to 3% of total engineering cost. The political cost of late-cycle revisions drops to roughly zero, which makes more iterative engineering possible.
- Structural effect: avoiding audit-remediation cost. My rough estimate is that the retrofit spends 10 to 25% of total engineering cost on audit remediation. Because Sylang is audit-ready by construction, I expect it to cut that by roughly an order of magnitude.
Program-level economics
Combine the three effects and here's my conservative working estimate for an organization moving from the conventional baseline to Sylang:
- Direct productivity gain on authoring: roughly 15 to 25% of total engineering cost
- Lower safety-case construction cost: roughly 4 to 7% of total engineering cost
- Avoided audit-remediation cost (compared with the retrofit): roughly 10 to 20% of total engineering cost
- Better iteration economics: hard to quantify but substantial, because late-cycle changes become workable rather than politically expensive
Subchapter 1.5 compresses the whole chapter into three paragraphs for an executive committee. Subchapter 1.6 maps the rest of the book to the four reader paths.
The companion repositories described in Chapter 4 and Appendix E are built to support exactly that kind of pilot.
1.5 The executive pitch
Subchapters 1.1 to 1.4 are the whole book in compressed form. If you need to decide whether to go further, three condensed versions help: a one-paragraph elevator pitch, a three-paragraph memo and a one-page brief for an architecture decision record. All three follow.
The one-paragraph version
On my estimates, it can cut total engineering cost of quality by 25 to 50%. The decision in front of you isn't whether to adopt AI in engineering; that's already made. It's whether to pursue the redesigned language in parallel with the retrofits the incumbent vendors are selling.
The three-paragraph version
Use this for a memo to an executive committee. It runs in three parts: Problem / Alternative / Action.
The Problem
Every regulated industry has been handed a board-level directive to bring AI into the safety-critical engineering workflow.
The dominant vendor response is to retrofit an LLM interface onto data models designed between 2005 and 2012 for human authors.
The retrofit produces artifacts that fail audit in three documented ways: schema drift, trace-link hallucination and audit-trail opacity.
My working estimate puts audit-remediation cost after a first audit cycle at 10 to 25% of total engineering budget. That roughly cancels the authoring gain the retrofit was bought to deliver.
The Alternative
The structural alternative is to redesign the modeling language so AI agents can be the primary author of artifacts that meet the relevant safety standards by construction.
Sylang is one such language. It has 22 file types, each in its own plain-text file, and 47 typed relationship keywords checked deterministically by one open-source validator. It also has a Markdown skill file per file type, which agents load on first encounter, so the language teaches itself.
Sylang has been demonstrated on four anchor projects: an Electric Parking Brake, autopilot envelope protection, an insulin infusion pump and a collaborative robot.
Each has been audited against ISO 26262, DO-178C, IEC 62304 and IEC 61508 respectively. My working estimate is that audit-remediation cost falls by roughly an order of magnitude compared with the retrofit.
▶ The Action
The decision isn't binary.
Pilot the redesigned language on a contained subsystem of 5 to 15 engineering FTE-years, while incumbent tools carry on with production programs.
Run the pilot for one full development cycle, including at least one audit milestone.
Measure the cost-of-quality categories from Subchapter 1.4 against an explicit baseline. Use the results to inform the program-wide adoption decision at the next strategic-planning cycle.
Expected timeline: 9 to 15 months from pilot start to adoption decision. I'm available to consult on pilot design.
The one-page version
Use this as an appendix to an architecture decision record, an RFP supplement or an executive leave-behind. It's built for scanning.
MBSE-for-AI: A Strategic Position
You adopt it incrementally. The language coexists with incumbent tools at the audit boundary.
Evidence behind the position
- Industry benchmarks (VDA QMC 2024; Capgemini World Quality Report 2024) put ASIL-D cost of quality at 27 to 32% of engineering budget. On my rough breakdown in Subchapter 1.4, verification, design and configuration make up 70 to 80% of the ASIL-D premium.
- Public benchmarks of LLM coding throughput (SWE-bench Verified, Nov 2025) underpin my working estimate of an end-to-end multiplier of 4 to 8× for ASIL-D authoring under Sylang's architectural conditions.
- My working estimate, not a measured result, is that the retrofit nets 0.8 to 1.4× once downstream costs count, against 4 to 8× for the redesigned language.
- Four anchor projects across automotive ASIL-D, aerospace DAL-A, medical Class C and industrial SIL-3 / PL-e demonstrate the approach across the four dominant regulatory regimes.
Recommendation
- Authorize a 90-day evaluation of Sylang on a contained subsystem of an active program, with an audit milestone scheduled within 12 months
- Name a pilot team of 3 to 7 engineers with a mixed skill profile (systems, software, safety), paired with an AI-engineering lead
- Measure against an explicit baseline for each cost-of-quality category, with the method agreed in writing before the pilot starts
- Reconvene at 90, 180 and 365 days to review findings. Make the program-wide adoption decision no earlier than the 365-day review
Risks and mitigations
| Risk | Likelihood | Severity | Mitigation |
|---|---|---|---|
| Pilot fails to demonstrate net productivity gain | Medium | Low (90-day cost contained) | Explicit measurement method; stop at the 90-day gate if early indicators are negative |
| Toolchain integration with incumbents proves intractable | Low | Medium | Sylang's plain-text artifacts allow mechanical export; choose a pilot subsystem with an explicit import/export boundary |
| Auditor unfamiliar with redesigned-language artifacts | High | Medium | Engage the auditor at pilot kickoff; provide a training package; structure .spec to mirror conventional document conventions |
| Open-source language abandoned by maintainer | Low | Medium | Artifacts are plain text and the language spec is open; an in-house team can maintain a vendored fork |
Pilot cost
What the rest of the book contains
Subchapter 1.6, the last in Chapter 1, gives the detailed reader-path table: which chapters matter most to each of the four main audiences.
Chapters 2 to 5 lay the foundations: concepts, the Sylang language reference, the IDE and the project-management constructs. Chapters 6 to 11 build the engineering spine across the four anchor projects. Chapters 12 to 15 cover the safety chain, and Chapter 16 the reactive-documentation approach to the safety case. Chapter 17 closes by restating the strategic argument in light of the evidence.
1.6 Reader paths
I wrote this book for four audiences, and each of you needs something different. Each path takes its own route through the remaining sixteen chapters. Follow the one for your role and you'll get the argument at the right depth, without detours through material meant for someone else.
Path 1: Engineering and program leaders
- Chapter 1 (this chapter, all of it): the argument and its numbers
- Chapter 2, subchapters 2.1 and 2.2 only: what MBSE is and why today's tools turned out the way they did. Skip 2.3 to 2.5 unless you work with regulatory affairs.
- Chapter 4, subchapters 4.1 and 4.2 only: build a working mental model of the IDE. Ask your pilot team to demo it rather than installing it yourself.
- Chapter 11 (the engineering spine end to end): a complete worked example that shows what a Sylang project looks like at full scope
- Chapter 17 (the closing argument): the argument restated with the evidence built up in the chapters between
Path 2: Working systems engineers
- Chapters 1, 2, 3, 4, 5: the foundations, in order
- Chapters 6, 7, 8, 9, 10: the engineering spine, in order (Chapter 8 is the longest and most consequential)
- Chapter 11: end-to-end integration on one slice of the EPB anchor
- Chapters 12, 13, 14, 15: safety engineering, in order
- Chapter 16: specification and dashboard files, and how the spine produces audit-grade reports
- Chapter 17: useful when you need to defend the method to leadership or auditors
Path 3: AI engineers building agent-based authoring pipelines
- Chapters 1, 2, 3: the argument and foundations. Chapter 3 is the formal specification of the language your agents will write.
- Chapter 4 (focus on the agent-integration sections): how the IDE exposes the model to the agent
- Chapter 5 (critical):
.agtand.sprare how agents get declared, dispatched and held accountable. You'll spend more time here than in any other chapter. - Chapters 8 (architecture) and 9 (requirements) in depth: the two artifact families where agent authoring pays off most
- Chapter 15: the coverage analysis behind the reviewer-agent design pattern
- Chapter 17: for making the architectural case to AI-skeptical engineering peers
Path 4: Functional-safety auditors and notified-body assessors
- Chapter 1 (all of it): the strategic context
- Chapter 3, subchapters 3.1, 3.2 and 3.6 only: the language's primitives, ontology and validator. Skip the detailed file-type sections; you'll meet them at the right depth in the safety chapters.
- Chapter 12 (the most consequential): the complete ISO 26262 safety chain in Sylang, with explicit reference to the clauses each artifact satisfies
- Chapters 13 (FMEA) and 14 (FTA): the two failure-analysis methods in Sylang form
- Chapter 15: coverage and consistency analyses that let you verify completeness without walking every artifact by hand
- Chapter 16: how the safety case you receive is materialized from current artifact state
- Chapter 17 (closing sidebar on machine-assisted audit): how the auditor's role changes as AI-authored safety cases become more common
Summary: the chapter map
Here's the complete chapter map with the reader paths overlaid. X marks a required chapter, ○ a recommended one, and a blank cell means you can skip it.
| Chapter | Topic | Leader | Engineer | AI builder | Auditor |
|---|---|---|---|---|---|
| 1 | TL;DR for leaders | X | X | X | X |
| 2 | MBSE from zero | ○ | X | X | ○ |
| 3 | The Sylang language | X | X | ○ | |
| 4 | Sylang Studio first project | ○ | X | X | |
| 5 | System project management | X | X | ||
| 6-10 | Engineering spine | X | ○ | ||
| 11 | Spine end-to-end | X | X | ○ | |
| 12 | ISO 26262 safety chain | ○ | X | ○ | X |
| 13 | FMEA | X | ○ | X | |
| 14 | FTA | X | ○ | X | |
| 15 | Traceability | X | X | X | |
| 16 | Reactive documentation | ○ | X | ○ | X |
| 17 | Closing argument | X | X | X | X |
This chapter argued that which AI tool should we buy for our MBSE stack? is the wrong question. The right one is what does our modeling language need to become for AI to be the primary author? Sylang answers it concretely, and on my estimates the economic case is big enough to justify organizational change.
Key takeaways
You’ve got this chapter if you remember:
- Asking which AI tool to buy for your MBSE stack is the wrong question; ask what your modeling language must become for AI to be the primary author.
- Incumbent MBSE tools struggle under AI authorship because of four design decisions (proprietary formats, save-time validation, implicit graphical semantics and external change management), and LLM retrofits inherit all four.
- When AI is the primary author, the bottleneck moves from authoring to review, so review has to become machine-mediated and version control becomes the system of record.
- My working estimate is a 25 to 50% cut in total engineering cost with Sylang, against a net 0.8 to 1.4x for retrofits; test it with a 90-day pilot.
- Pick the reader path for your role, because leaders, engineers, AI builders and auditors each have their own route through the book.
Check yourself
Answer in your head first, then reveal.
1What three failure modes show up when an LLM writes artifacts through a tool built for human authors?
Schema drift, trace-link hallucination and audit-trail opacity. Each one can get the artifact rejected at audit.
2Why doesn't the authoring speedup from an LLM retrofit carry through to the whole program?
Heavier review, rework from schema drift and audit remediation eat into it, because the underlying data model was designed for human authors.
3What does Sylang's
.specfile type change about the safety case?The safety case is computed from queries over current artifacts, so it re-materializes when they change. The safety manager curates the queries instead of producing a document.
4What should you do before committing to a program-wide switch?
Run a 90-day pilot on a contained subsystem, measured against an explicit baseline for each cost-of-quality category.